
Suno Speech Beta: Revolutionizing AI Audio Generation
The Launch of Suno Speech
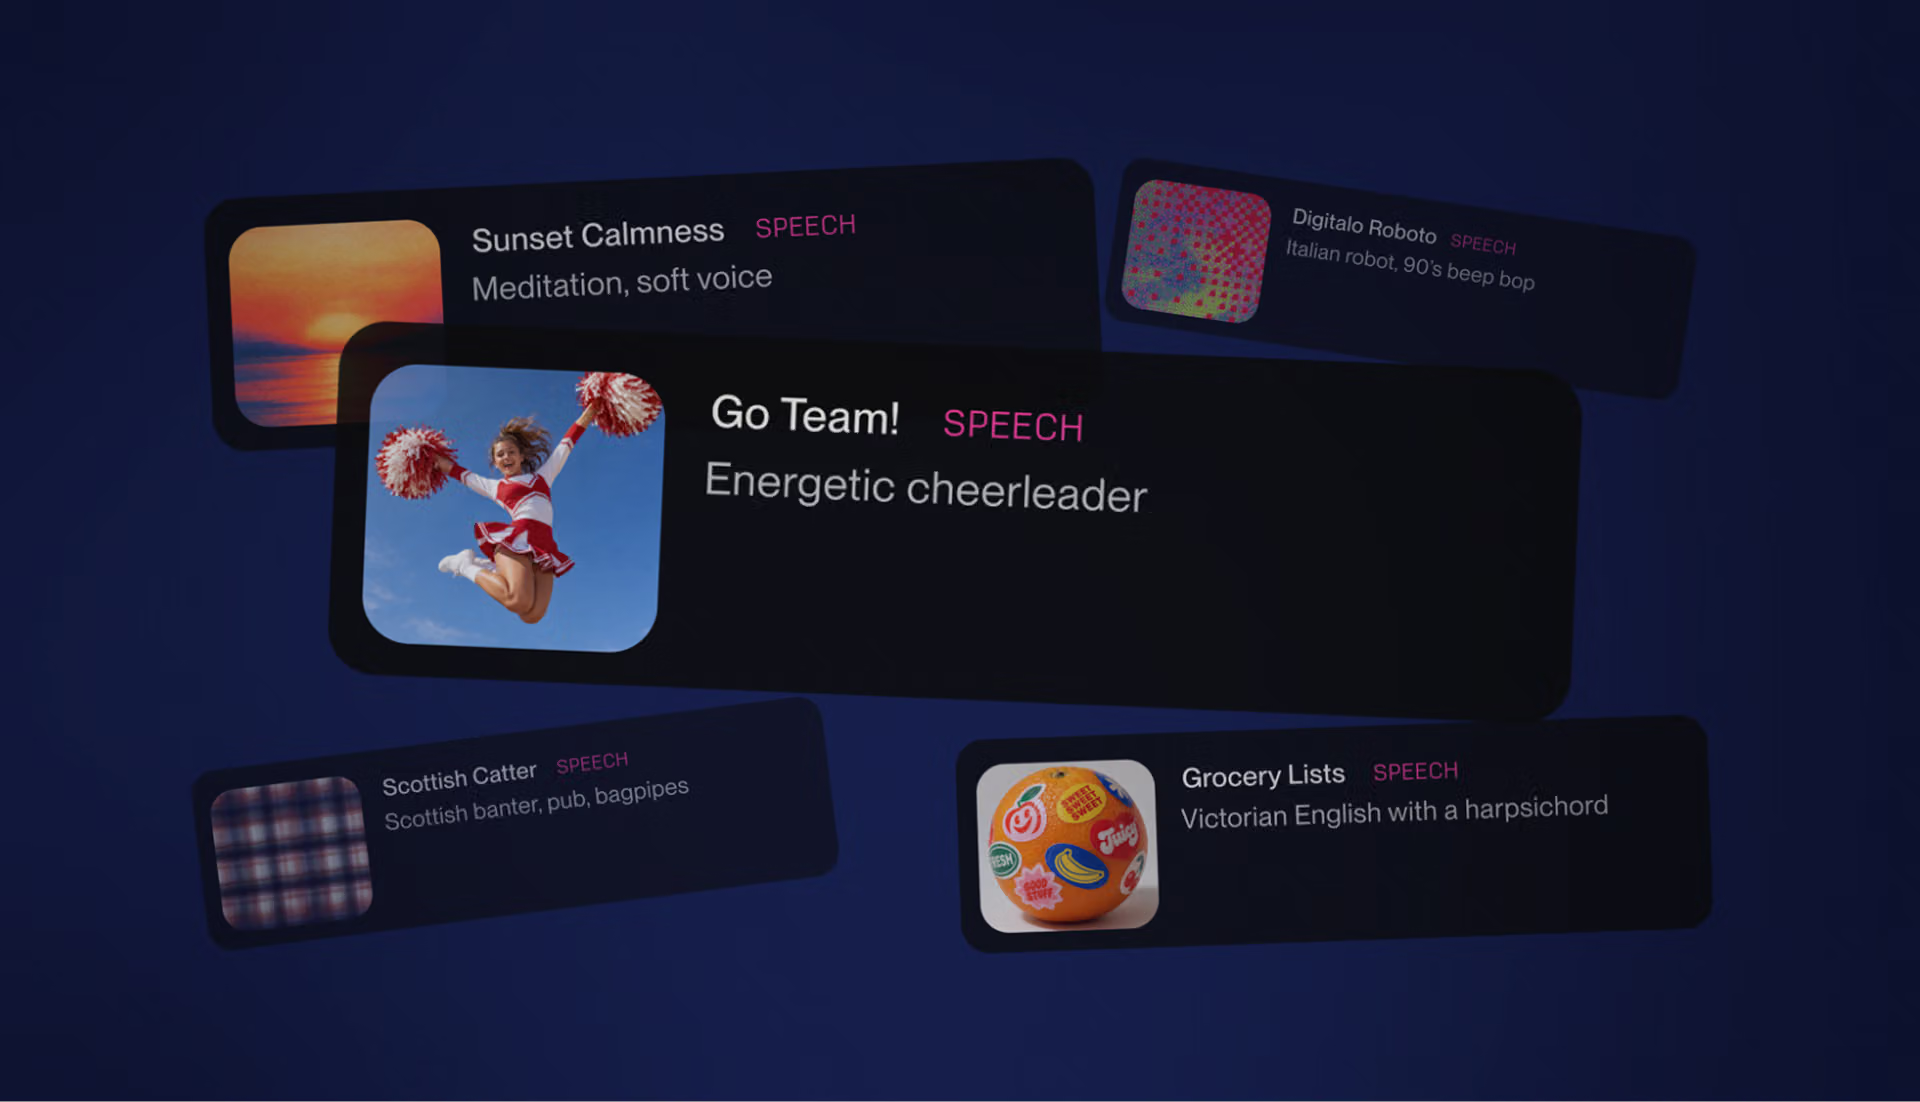
Recently, the prominent artificial intelligence music platform Suno officially announced an exciting new feature. Suno proudly proclaims this remarkable innovation as a true industry first. It uniquely generates voice and music together as a single, coherent track.
A Breakthrough in Audio Processing
Interestingly, this sophisticated system entirely bypasses traditional workflows. These older methods merely stitch text-to-speech outputs over background music. Instead, it utilizes an advanced end-to-end integrated generation process. Consequently, it stands as a pioneering closed-source audio model. It uniquely delivers a flawlessly fused combination of spoken narration and original music in a single pass.
Opening to the Public
Over the past month, the company carefully tested this groundbreaking feature with select early adopters. Following this successful trial, Suno is officially introducing Speech Beta to the general public for widespread exploration.
How to Use the New Feature
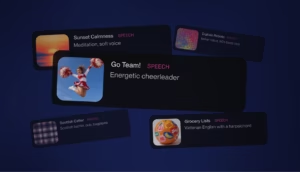
Official representatives state that users can effortlessly craft captivating spoken audio. This audio comes beautifully accompanied by rich background music. Furthermore, developers have seamlessly integrated this powerful tool directly into the primary interface. Creators simply need to input a fleeting inspiration, a beautiful poem, or a compelling narrative. Subsequently, they just describe their desired vocal characteristics and preferred musical style. This simple action instantly initiates the creative process.
Current Limitations and Future Updates
However, the development team transparently acknowledged a few notable limitations within the current iteration. For instance, the system occasionally exhibits slight accent instability during longer generations. A distinct British accent might unexpectedly drift into an Australian cadence before reverting. Additionally, the vocal intonation and emotional pauses sometimes appear overly dramatic. As a result, this theatrical delivery can inadvertently cause excessively slow phrasing and disrupted pacing.