
Arena Platform Unveils the Latest AI Large Model Rankings
The Arena platform (arena.ai) has officially published its artificial intelligence large model leaderboard for the 41st week of 2026, encompassing the evaluation period from October 5 to October 11. In this latest iteration, the entirely new Claude Opus 5.5 Max from Anthropic captured the paramount position upon its inaugural entry into the agent rankings. Simultaneously, domestic models such as Kimi K3 Max firmly secured their places within the top 20 of the comprehensive leaderboard. Several other domestic creations, notably Qwen 3.8 Max, maintained remarkably stable standings, firmly situating themselves within the upper-middle echelon of the global competition.
Notably, this prestigious ranking derives from anonymous, blind-tested voting on the platform. It utilizes the ELO rating system (or a percentage signal for the agent category) to calculate standings, thereby reflecting subjective user preferences rather than absolute capability metrics. The distinct sub-rankings remain entirely independent, precluding cross-category comparisons. Minor score differentials within the statistical margin of error signify a technical tie. Furthermore, newly introduced models must amass a requisite volume of votes before achieving formal inclusion.
Comprehensive Leaderboard Overview
The vanguard of the comprehensive leaderboard remains relatively undisturbed this week. Gemini 4 Argon High continues to dominate the apex, sustaining an impressive ELO score of 1525. Anthropic successfully secured multiple coveted positions within the top four. Claude Opus 5.5 High ascended two places to claim the runner-up spot with an ELO score of 1507. Although a gap exists between it and the reigning champion, the differential falls within a 30-point margin, rendering it statistically adjacent to the third-place Claude Opus 4.6 High.
This edition welcomes the addition of GPT 5.5 and Gemini 3.5 Flash Medium, which elegantly claimed the 29th and 30th positions, boasting ELO scores of 1477 and 1476, respectively.
Domestic models collectively occupy the upper-middle percentiles, displaying a steadfast hierarchy:
- Moonshot Kimi K3 Max: Achieved the highest domestic placement at 16th, holding steady with an ELO of 1488.
- Alibaba Qwen 3.8 Max: Secured the 22nd rank at 1483, rising one spot from the preceding week.
- Xiaomi MiMo V2.6 Pro: Maintained the 26th position with an ELO of 1480.
- Zhipu GLM 5.3 Max: Retained the 27th slot with an ELO of 1478.
The Coding Leaderboard
Gemini 4 Argon High continues its uncontested reign atop the coding leaderboard, experiencing a marginal two-point increase to reach an ELO of 1562. The Anthropic models exhibited profound upward momentum; Claude Opus 5.5 High surged an astonishing seven places to penetrate the top five. It garnered 1550 points, trailing the second-place Claude Fable 5 High (1551 points) by a mere fraction, constituting a statistical tie. Zhipu’s GLM 5.3 Flash ascended two places to 27th with 1525 points, emerging as the preeminent domestic model in this complex domain. The newly introduced Claude Opus 4.5 made its debut at 30th with an ELO of 1523.
Other notable domestic coding performances include:
- Kimi K3 Max: 10th place (ELO 1540).
- MiMo V2.6 Pro: 11th place (ELO 1539).
- DeepSeek V4.1 Flash Max: 26th place (ELO 1528).
- Qwen 3.8 Max: 29th place (ELO 1524).
Front-End Development Leaderboard
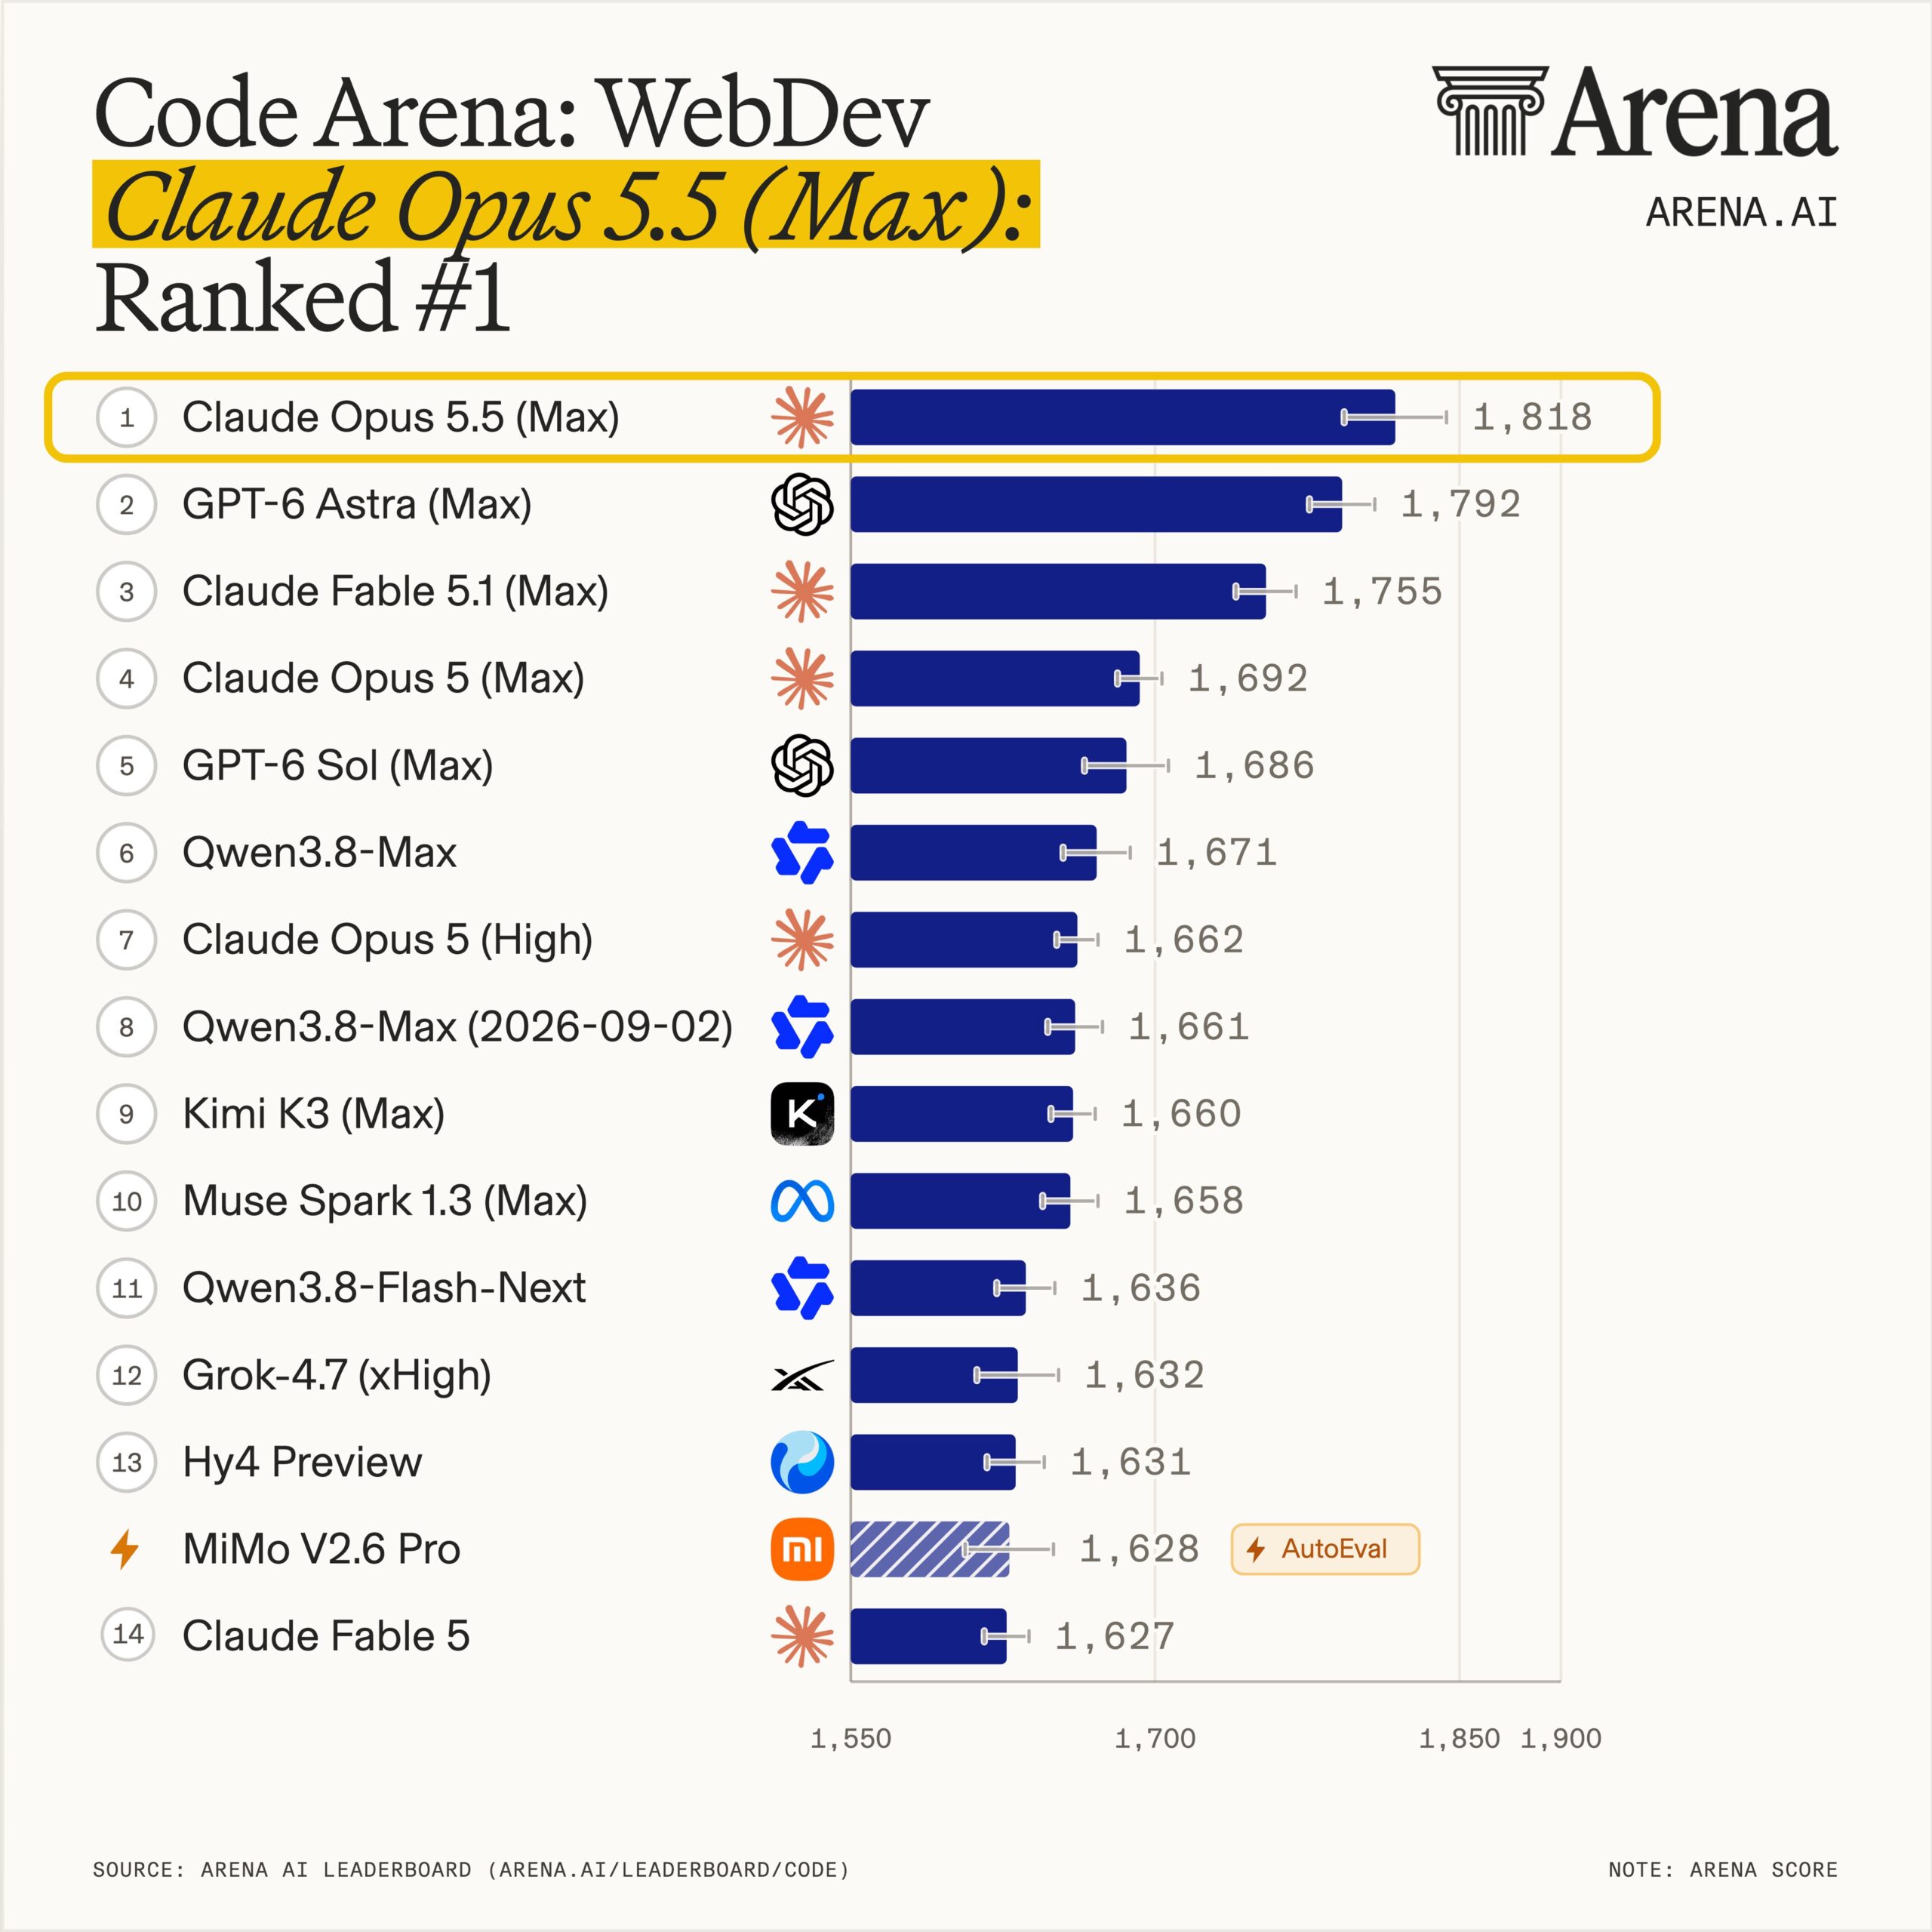
The upper echelons of the front-end development hierarchy remain resolute. Claude Opus 5.5 Max perpetuates its dominance at the pinnacle with an ELO of 1813, wielding a substantial advantage. Among domestic contenders, Xiaomi’s MiMo V2.6 Flash gracefully entered the chart at 16th with 1637 points. Furthermore, MiMo V2.6 Pro leaped five places to 19th with 1629 points, demonstrating stellar performance. Alibaba’s Qwen 3.8 Max 0902 rose to 10th, and Qwen 3.8 Max secured 11th; both models triumphantly breached the top 15, illustrating the unceasing advancement of domestic front-end capabilities.
Intelligent Agent Leaderboard
The agent rankings witnessed monumental shifts this cycle. Anthropic’s Claude Opus 5.5 Max dramatically seized the crown upon its debut, boasting a remarkable net improvement rate of 15.53 percent. It achieved an extraordinary task confirmation success rate of 17.29 percent, while its tool hallucination rate plummeted to a mere 0.37 percent. Claude Opus 5.5 High defended the second position, whereas GPT 6 Astra Max climbed to third. Gemini 4 Argon High ascended to eighth; remarkably, its 0.18 percent tool hallucination rate represents the lowest among all elite models evaluated.
Domestic models presently navigate the second tier of the agent rankings:
- DeepSeek V4.1 Flash Max: Ranked 17th with a 3.80 percent net improvement.
- Kimi K3 Max: Ranked 18th with a 3.78 percent net improvement.
- Tencent Hy4 Preview: Ranked 19th with a 3.61 percent net improvement.
- MiMo V2.6 Pro: Ranked 20th, ascending one spot with a 3.52 percent net improvement.
- Qwen 3.8 Max: Ranked 24th with a 2.35 percent net improvement.
AI Image and Video Generation
OpenAI models monopolize the upper tier of the image generation chart. GPT Image 2.5 Sunburst securely anchors the first position with an ELO of 1425, eclipsing the runner-up by over 20 points. Google’s Gemini Nano Banana 2.1 entered the fray this week, securing a respectable sixth place on its maiden voyage with 1328 points. Domestic models such as ByteDance’s Seedream 5.0 Pro (12th) and Alibaba’s Qwen Image 3.0 Pro (13th) reside comfortably in the upper-middle spectrum.
Regarding video generation, Google firmly retains control. Gemini Omni 1.1 Flash and Gemini Omni Flash occupy the top two positions, both surpassing an ELO of 1510. Domestic models performed exceptionally well, with six variants penetrating the top 20. ByteDance’s Dreamina Seedance 2.0 claimed fifth, Alibaba’s Wan 3.0 secured sixth, and Dreamina Seedance 2.5 took seventh. Their unwavering stability profoundly highlights the formidable global competitiveness of domestic AI video generation frameworks.
Weekly Overview and Future Prospects
Surveying the entirety of this week’s charts, the novel models under the Anthropic umbrella demonstrated formidable prowess. You can explore the official Arena leaderboard updates to see how Claude Opus 5.5 Max orchestrated a spectacular debut by instantly claiming the throne on the agent chart. Furthermore, Claude iterations monopolized the premier positions across numerous specialized rankings, tilting the competitive landscape heavily toward Anthropic.
Domestic models preserved a dignified stability, with distinct echelons remaining clearly delineated. Stalwarts like Kimi K3 Max and Qwen 3.8 Max consistently dominate the upper-middle tiers, while fresh additions like MiMo V2.6 Flash seamlessly integrated into the rankings. This graceful progression perfectly encapsulates the relentless, iterative rhythm of domestic model development. Analysts fervently anticipate further version updates from global developers in the forthcoming week, warranting vigilant observation of subsequent ranking transformations.